Enterprise document search often struggles with fragmented answers, lost table formatting, and brittle vector pipelines when querying complex policy manuals, technical specifications, and legal binders. A long context window Gemini integration fundamentally alters this paradigm by enabling engineering teams to ingest entire document corpora—up to two million tokens in Gemini 1.5 Pro—directly into the model active attention window. Instead of relying on lossy text chunking and semantic similarity heuristics, organizations can execute deep reasoning across comprehensive reference libraries with near-perfect factual recall, verifiable citations, and complete structural context.
Why Traditional RAG Pipelines Fail on Complex Enterprise Documents
Standard enterprise document search architecture frequently relies on Retrieval-Augmented Generation (RAG) pipelines that ingest files by slicing text into arbitrary token chunks. While effective for simple question-answering over unstructured articles, this approach introduces acute failure modes when applied to dense technical specifications, regulatory filings, financial ledgers, and nested contracts.
The Failure Modes of Chunking, Embedding, and Metadata Extraction
Traditional chunking strategies—whether fixed-size, recursive, or sentence-based—consistently break the syntactic and semantic coherence of complex records. Tables lose their header definitions across chunk boundaries, multi-page financial calculations become decoupled from their explanatory footnotes, and nested lists lose their hierarchical parent nodes. Furthermore, embedding models compress hundreds of words into a single dense vector, effectively washing out fine-grained distinctions, numerical values, and specific clause conditions. When engineering teams build metadata extraction layers to mitigate this loss, the resulting pipeline becomes fragile: custom extractors require continuous maintenance as source document layouts drift.
Where Vector Similarity Loses Cross-Document Context and Structural Reasoning
Vector search evaluates cosine similarity between a query embedding and isolated chunk vectors, retrieving only the top-k nearest fragments. This retrieval mechanism fails on questions that require global synthesis or structural deductions across non-contiguous passages, such as identifying conflicting liability clauses across distinct vendor agreements. In the debate of rag vs gemini long context window architectures, isolated chunks lack cross-document awareness. When an answer depends on reconciling three distinct sections across a 200-page manual, top-k retrieval often drops intermediate premises, leading models to hallucinate plausible bridges across missing facts.
How Long Context Window Gemini Integration Replaces Brittle RAG
Modern generative systems no longer require complex chunking heuristics to interrogate multi-megabyte reference documents. With a long context window Gemini integration, development teams can supply comprehensive files directly into the prompt context, replacing multi-tier retrieval stacks with direct neural attention.
Bypassing Vector Databases with Gemini's 2M-Token Window
Operating an enterprise vector database requires maintaining embedding models, ingestion workers, chunk indexing queues, synchronization jobs, and vector distance recalculations. As detailed in the Google Cloud long context documentation, Gemini models support up to 2 million tokens in Gemini 1.5 Pro, demonstrating near-perfect retrieval accuracy exceeding 99% across extensive token spans. In this gemini 2 million token context guide, engineering teams eliminate vector stores by loading entire documentation trees, code repositories, or policy libraries directly into memory. Removing vector indices eliminates vector drift, out-of-sync database replicas, and index rebuilding scripts whenever source documentation is updated.
Whole-Corpus Ingestion vs. Lossy Top-K Semantic Retrieval
When an entire document collection resides within the active context window, the model performs cross-attention across all tokens simultaneously. Rather than relying on top-k cosine similarity heuristics to guess which three paragraphs might contain an answer, Gemini evaluates relationships between disparate chapters, tabular annexes, and historical amendments. For example, if an enterprise master service agreement defines an indemnity cap on page 12 and overrides it under specific warranty conditions on page 84, whole-corpus ingestion guarantees that both clauses are parsed together in context. At Canvas Developers, our engineers utilize LLM integration design patterns that preserve raw document structure—including markdown tables, XML tags, and document hierarchies—allowing the model to reason over complete semantic landscapes without lossy summarization.
Architecting Enterprise Document Search with the Gemini API
Building a robust search and retrieval system on top of Google generative models requires careful payload design and runtime cache orchestration. By decoupling corpus ingestion from per-request inference, teams can turn raw files into responsive enterprise intelligence.
Structuring Multi-Document Payloads and System Instructions
When orchestrating enterprise document processing gemini api workflows, document payloads must be formatted to preserve semantic boundaries and provenance. Rather than concatenating raw text into an unstructured stream, engineers wrap documents in clear structural delimiters such as XML or Markdown fences with distinct attributes: <document id="hr-policy-202" category="compliance">. System instructions should be declared explicitly to govern how the model searches this corpus. Strict behavioral guidelines instruct the model to ground every assertion in a verified document identifier, cite paragraph or section markers, and explicitly declare when an answer cannot be determined from the loaded materials. This structuring eliminates ambiguity, enforces deterministic citations, and prevents hallucinated extrapolations across enterprise records.
Implementing Gemini Context Caching for Reusable Reference Corpora
Sending a 500,000-token payload with every user prompt introduces severe financial and latency overheads. The Google AI developer platform solves this through explicit context caching, documented in the Gemini API context caching documentation. Using explicit caching via client.caches.create, engineering teams upload an enterprise reference library once, configure a Time-To-Live (TTL, default 60 minutes), and obtain a reusable cache identifier. Subsequent queries reference this cached token prefix at a fraction of standard input token rates, paying an hourly storage fee per million tokens while the cache remains active.
Context caching also addresses gemini 1.5 pro large context latency challenges. Under un-cached conditions, processing hundreds of thousands of input tokens requires the model to compute key-value (KV) attention maps from scratch for every call, elevating time-to-first-token (TTFT) metrics into tens of seconds. Context caching persists the precomputed KV tensors in accelerator memory, reducing first-token latency in high-throughput search scenarios to sub-second or low-second response windows. At Canvas Developers, our engineers automate cache warm-up and TTL extension routines through custom cloud infrastructure pipelines, ensuring reference corpora remain hot during peak business operating hours.
Cost and Latency Economics: RAG vs. Gemini Long Context with Caching
Evaluating the economics of enterprise search requires examining both infrastructure overhead and per-query operational expense. While traditional vector pipelines appear low-cost on raw token consumption, maintaining dedicated indexing clusters often creates significant operational friction compared to cached long-context architectures.
Gemini Context Caching Pricing vs. Dedicated Vector Database TCO
A production vector search stack carries substantial total cost of ownership (TCO). Engineering teams must provision and maintain dedicated vector database instances, ingestion workers, embedding calculation pipelines, and re-indexing infrastructure. When source policies or technical manuals change, chunk collections must be invalidated, re-embedded, and re-indexed across vector clusters. In contrast, under official Gemini API context caching pricing structures, costs divide cleanly into cache storage and discounted query inference. Users pay an hourly storage fee per million tokens alongside standard prompt creation fees, while subsequent queries hitting the cached context receive a 75% to 90% reduction on input token charges. For high-frequency enterprise workflows where teams repeatedly interrogate the same compliance library or product catalog throughout the workday, gemini context caching pricing delivers predictable expenditure while removing database cluster maintenance entirely.
Latency Profiles Across 100K to 2M Token Working Sets
Query latency in long-context models correlates directly with prompt length and caching state. Un-cached requests across large token sets force the model to recompute key-value (KV) attention matrices from scratch, creating time-to-first-token (TTFT) delays that scale with prompt volume. On a 100,000-token un-cached payload, latency remains manageable for batch analysis, but scaling toward a full 2,000,000-token working set can push un-cached TTFT into tens of seconds. Context caching fundamentally alters these latency profiles by persisting precomputed KV states in accelerator memory, reducing TTFT across 500,000 to 1,000,000 token working sets down to low-second response windows.
When weighing the trade-offs of rag vs gemini long context window architectures, organizations managing tens of millions of historical tokens should consider a hybrid retrieval pattern. Rather than attempting to maintain multi-million-token contexts indefinitely, teams use deterministic metadata filtering or lightweight lexical indexing to select a focused 500,000-token reference corpus, which is then loaded into a cached Gemini session for exhaustive, high-fidelity reasoning.
Enterprise Implementation Risks: What AI Coding Won't Solve Alone
Accelerating development with autonomous coding agents allows teams to prototype LLM integrations rapidly, but generating code through prompts does not guarantee enterprise-grade resilience. Designing a production document retrieval system requires disciplined human engineering oversight.
Where AI Coding Speeds Delivery and Where Automated Code Fails
In modern engineering teams, AI coding agents and harnesses like Antigravity accelerate initial boilerplate generation, API client scaffolding, and test suite creation. In an enterprise document processing gemini api implementation, automated coding tools excel at generating typed schema bindings, structuring JSON payloads, and stubbing mock endpoints. However, automated code generation fails when resolving complex concurrency conditions, handling distributed state, or designing resilient rate-limiting backoffs. AI assistants frequently generate naive retry loops that cause cascading request spikes against upstream API quotas, or write context-caching routines that silently leak memory when cache renewal loops fail. At Canvas Developers, AI tools speed up delivery while experienced engineers direct the work, own the system architecture, review every commit, and make final release decisions.
Human Verification Must-Haves: Tenant Isolation, Access Controls, and Data Security
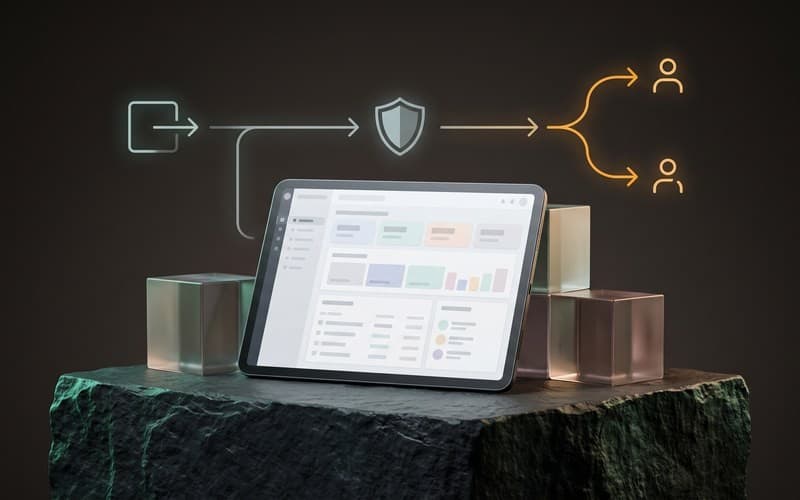
A secure enterprise document search architecture must enforce strict boundary controls before any document enters an LLM context. Automated code generation cannot verify organizational compliance or multi-tenant boundary integrity. Human engineers must design and rigorously test three critical security layers:
- Tenant Isolation: Preventing cross-tenant data contamination by strictly binding cache IDs to cryptographically validated enterprise tenant tokens, preventing unauthorized users from accessing cached contexts.
- Attribute-Based Access Control (ABAC): Ensuring documents are filtered against caller permissions before context assembly, ensuring confidential executive compensation or legal documents are never exposed in shared caches.
- Production Resilience and Graceful Fallback: Handling cache eviction (when a TTL expires during prolonged queries) through automated cache recreation pipelines, and implementing exponential backoff when encountering Gemini API rate limits.
To establish production confidence, engineering teams should follow a subject-specific acceptance checklist: validating tenant boundaries under concurrent load, executing automated prompt-injection tests, verifying payload redaction of sensitive personally identifiable information (PII), and confirming sub-second fallback when cached sessions expire.
Productionizing Your Gemini Search: Scoping Architecture and Next Steps
Transitioning from experimental notebooks to a hardened search platform requires selecting an architectural pattern aligned with your security posture and data governance constraints. Organizations evaluating a long context window gemini integration typically choose between two engineering delivery models based on compliance demands:
For strictly regulated industries with strict data residency mandates, a Private / Local AI Engineering workflow deploys models directly within infrastructure the client controls or within an agreed isolated cloud tenancy. For enterprise software products prioritizing rapid feature releases, a commercial cloud workflow—such as our Claude Code / OpenAI Codex Engineering model—leverages commercial AI APIs with pre-approved security boundaries and automated verification harnesses. In both models, AI-assisted scaffolding shortens initial feedback loops, while experienced engineers conduct manual code reviews and enforce strict acceptance criteria.
Canvas Developers builds, stabilises, and hardens enterprise AI search systems from our office in Dhaka, directing AI coding agents under strict senior engineering leadership. Engagements begin with a transparent scoping phase, progressing through agreed milestones, comprehensive penetration testing, and formal handover. If your team is evaluating whether to replace a brittle vector pipeline or harden an existing prototype, submit your existing technology stack, document volume, and performance requirements through our contact form or explore our LLM integration services to request a scoped architecture assessment.