Retrieval helps; it does not guarantee a correct answer
Retrieval-augmented generation (RAG) supplies selected documents to a language model before it answers. It can make an answer more relevant to a business's information, but the system can still retrieve the wrong passage, miss an exception or generate a claim the source does not support.
Begin with a defined job: for example, helping support staff find a current returns policy. Decide which sources are authoritative, who maintains them and when an answer needs human review. A general instruction to “use our documents” is not an acceptance criterion.
Prepare and retrieve usable evidence
Preserve headings, document identity, version and source links when dividing documents into passages. Keep exceptions with the rule they qualify. Compare keyword, vector and combined retrieval against representative questions instead of assuming one method or a fixed chunk size is always best. Test whether the required evidence appears in the retrieved results separately from whether the final response uses it accurately. See Microsoft's RAG architecture overview.
Apply permissions before text reaches the model
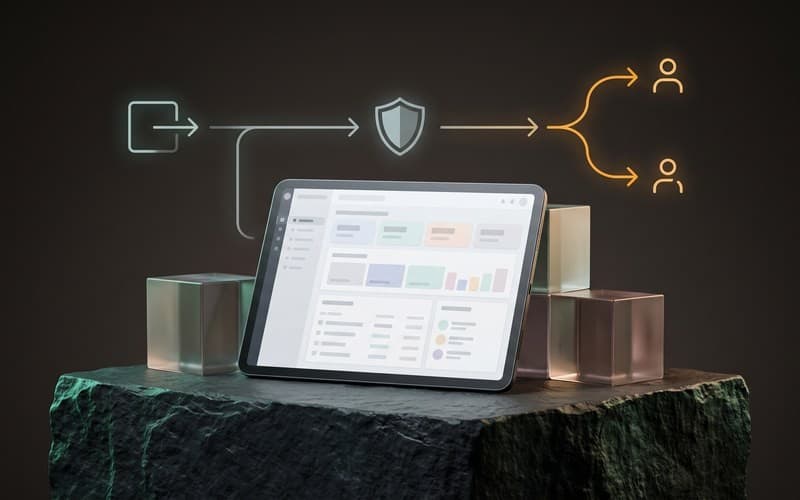
Restrict retrieval using the authenticated user's tenant and document permissions. A prompt telling the model to hide confidential material is not an authorization boundary. Source links, generated summaries, conversation history and cached answers also need access checks. Permission changes and document deletion must propagate to the index and any derived storage.
For an implementation example, Azure AI Search documents query-time permission filtering. Its platform-specific capabilities and preview limitations need checking for the intended deployment.
Make unsupported questions an explicit outcome
Show the passage behind a material claim and let the user inspect it. A citation is useful only when it actually supports the answer. If the sources are missing, contradictory or out of date, say what could not be established and offer a relevant search result or a handoff. Do not turn a weak retrieval score into a made-up confidence percentage.
Example: a policy says unopened items can be returned within 30 days but says nothing about international return postage. For “Will you reimburse my overseas postage?”, a suitable answer identifies that missing information and points to the policy or support team. Repeating the 30-day rule does not answer the question.
Evaluate the full behavior
- Include answerable, ambiguous, outdated and deliberately unsupported questions.
- For each case, record the expected evidence, allowed user role and acceptable answer or abstention.
- Check retrieval coverage, support for individual claims, citation accuracy, permission leakage, latency and cost separately.
- Repeat the set after changing documents, retrieval settings, prompts or models. Add real failures after removing unnecessary personal data.
This is a proposed evaluation approach, not a claim about a historical client dataset. No finite test set proves that future answers will always be correct. High-impact actions need additional controls, approval or human review appropriate to the workflow.
Explore LLM integration for an AI feature inside an application, or workflow automation when the job crosses several systems. The development tool environment and the deployed product's data flow are separate decisions.