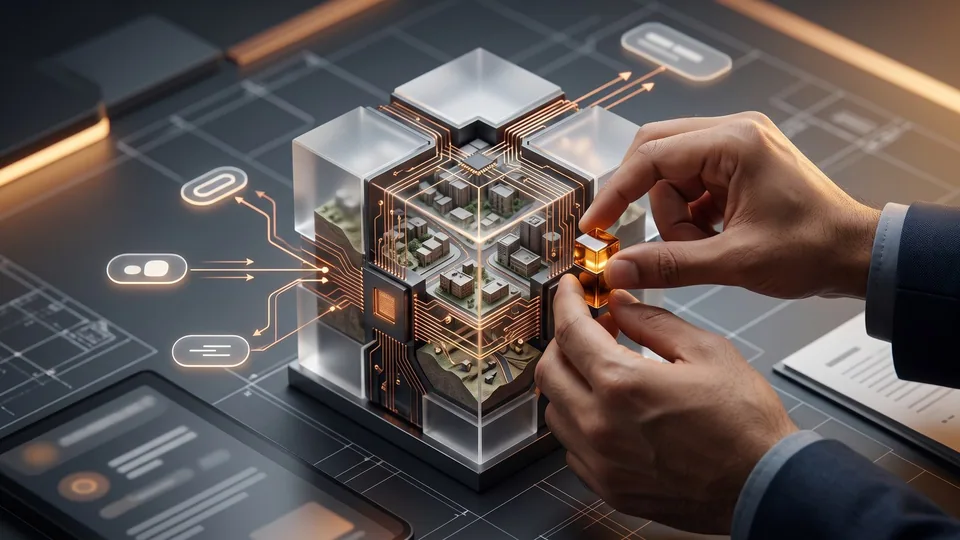
This illustrative example is a conceptual product architecture designed by Canvas Developers to demonstrate how enterprise engineering teams can structure a high-throughput real estate API integration platform. It is not delivered client work. Real estate investment firms, underwriting desks, and valuation platforms routinely struggle with fragmented municipal deeds, assessor databases, and active listing streams. This blueprint models a unified microservice architecture that aggregates heterogeneous public records and commercial feeds into a low-latency querying layer.
Project at a Glance: What Does This Proptech Integration Engine Deliver?
Designed for proptech ventures, institutional asset managers, and automated valuation platforms, this concept demonstrates an enterprise real estate API integration platform built to process high-volume property records. The engineering scope centers on unifying disparate parcel datasets—including assessor tax rolls, deed transfers, and live market inventory—into a standardized data fabric.
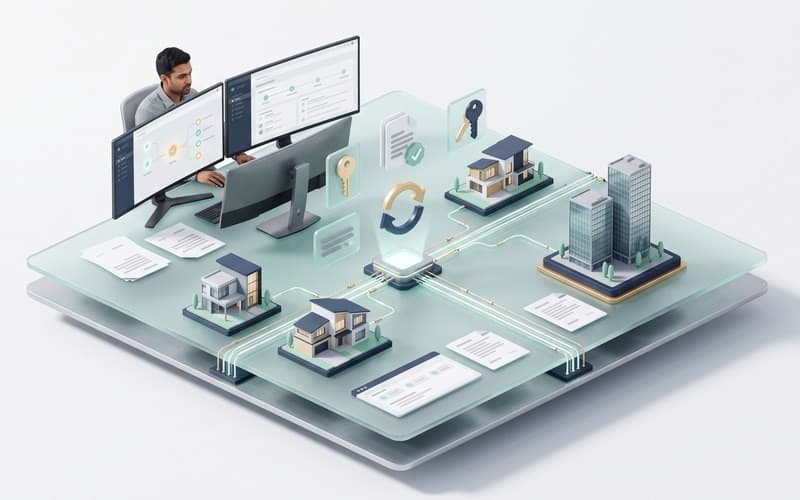
As a unified proptech listing aggregator, the platform normalizes heterogeneous upstream sources such as RealEstateAPI documentation endpoints, secondary REAPI feeds, and commercial marketplace listings into unified schemas. By decoupling third-party schema ingestion from consumer-facing query interfaces, the architecture ensures resilient downstream delivery for valuation engines and property search tools.
The Brief: How Do You Harmonize Fragmented Property Registries at Scale?
Building a resilient nationwide property search engine requires solving acute data fragmentation. Across municipal jurisdictions, county recorder offices store parcel boundaries, deed transfers, and tax assessments in conflicting formats with inconsistent field naming and missing geographic attributes. At the same time, commercial listing feeds refresh continuously with active asking prices and listing statuses.
Integrating these disparate registries into an automated property valuation pipeline presents severe throughput, spatial geocoding, and latency constraints. Ingestion pipelines must normalize thousands of varied tax and parcel data points across tens of millions of residential records, resolving unformatted Assessor Parcel Numbers (APNs) and coordinate projections without bottlenecking downstream comparative analytics.
Approach & Process: How Does Human-Directed AI Engineering Accelerate Data Pipelines?
To construct this real estate API integration platform efficiently, Canvas Developers applies human-directed AI workflows. AI coding agents and an advanced engineering harness accelerate the generation of routine data ingestion connectors, interface boilerplate, and schema transformation mappers across municipal data dictionaries. Depending on enterprise security requirements, teams deploy these workflows through Private / Local AI Engineering using isolated open-weight models or commercial Claude Code and OpenAI Codex environments under client-approved policies.
However, automated tools cannot replace domain expertise in complex data plumbing. Experienced software engineers direct every pipeline phase, defining the microservice topology, resilient message queues, and strict schema contracts. Senior engineers review every pull request, enforce type safety, and govern release decisions to ensure real estate analytics integration feeds maintain data consistency before reaching staging environments.
What Was Built: How Does the Unified GraphQL Layer Power Sub-100ms Evaluations?
The conceptual architecture centers on a unified GraphQL layer that queries normalized parcel-level deeds, mortgages, and tax assessments. Instead of managing multiple REST endpoints across county tax recorders, client applications query a federated schema. This interface powers an interactive real estate valuation API dashboard featuring a synchronized dual-pane layout: a geospatial map rendering parcel boundaries alongside side-by-side comparative valuation panels with historical deed timelines and assessor roll breakdowns.
Beneath the interface, an automated property valuation pipeline executes deterministic record deduplication and spatial geocoding. Ingestion workers resolve disparate County FIPS codes, unformatted Assessor Parcel Numbers (APNs), and boundary coordinates into persistent entity records. To support high throughput across tens of millions of residential records, distributed Redis caching clusters store pre-aggregated property summaries, delivering sub-100ms comparative market evaluations across active search queries.
Technical Realities: Where Does Automation Excel and What Demands Human Oversight?
While AI tools rapidly scaffold parsers and connectors, data engineering presents challenges automation cannot solve alone. Municipal feeds frequently experience schema drift, missing parcel values, and undocumented formatting shifts. For mission-critical real estate analytics integration, unhandled upstream discrepancies can corrupt valuation algorithms and underwriting calculations.
Senior human oversight remains essential for system stability. Experienced engineers design resilient fallback strategies, validate database indexing, and audit data security across tenant boundaries. In any enterprise real estate API integration platform, human code review ensures caching topologies and pipelines scale reliably under heavy traffic.
Next Steps: How Can You Scope and Build a Custom Proptech Integration Platform?
Transitioning this concept into an active nationwide property search engine follows a structured, milestone-based engineering path. Engagements begin with technical scoping, progressing through connector development, rigorous QA, and cloud deployment.
Whether building an MVP or deploying a high-throughput real estate API integration platform, Canvas Developers pairs human engineering leadership with AI-assisted acceleration. To evaluate your data aggregation requirements, schedule a scoped technical assessment through the contact form at Canvas Developers or reach out via WhatsApp on the website.